Why is caching variables in AWS Lambdas important?
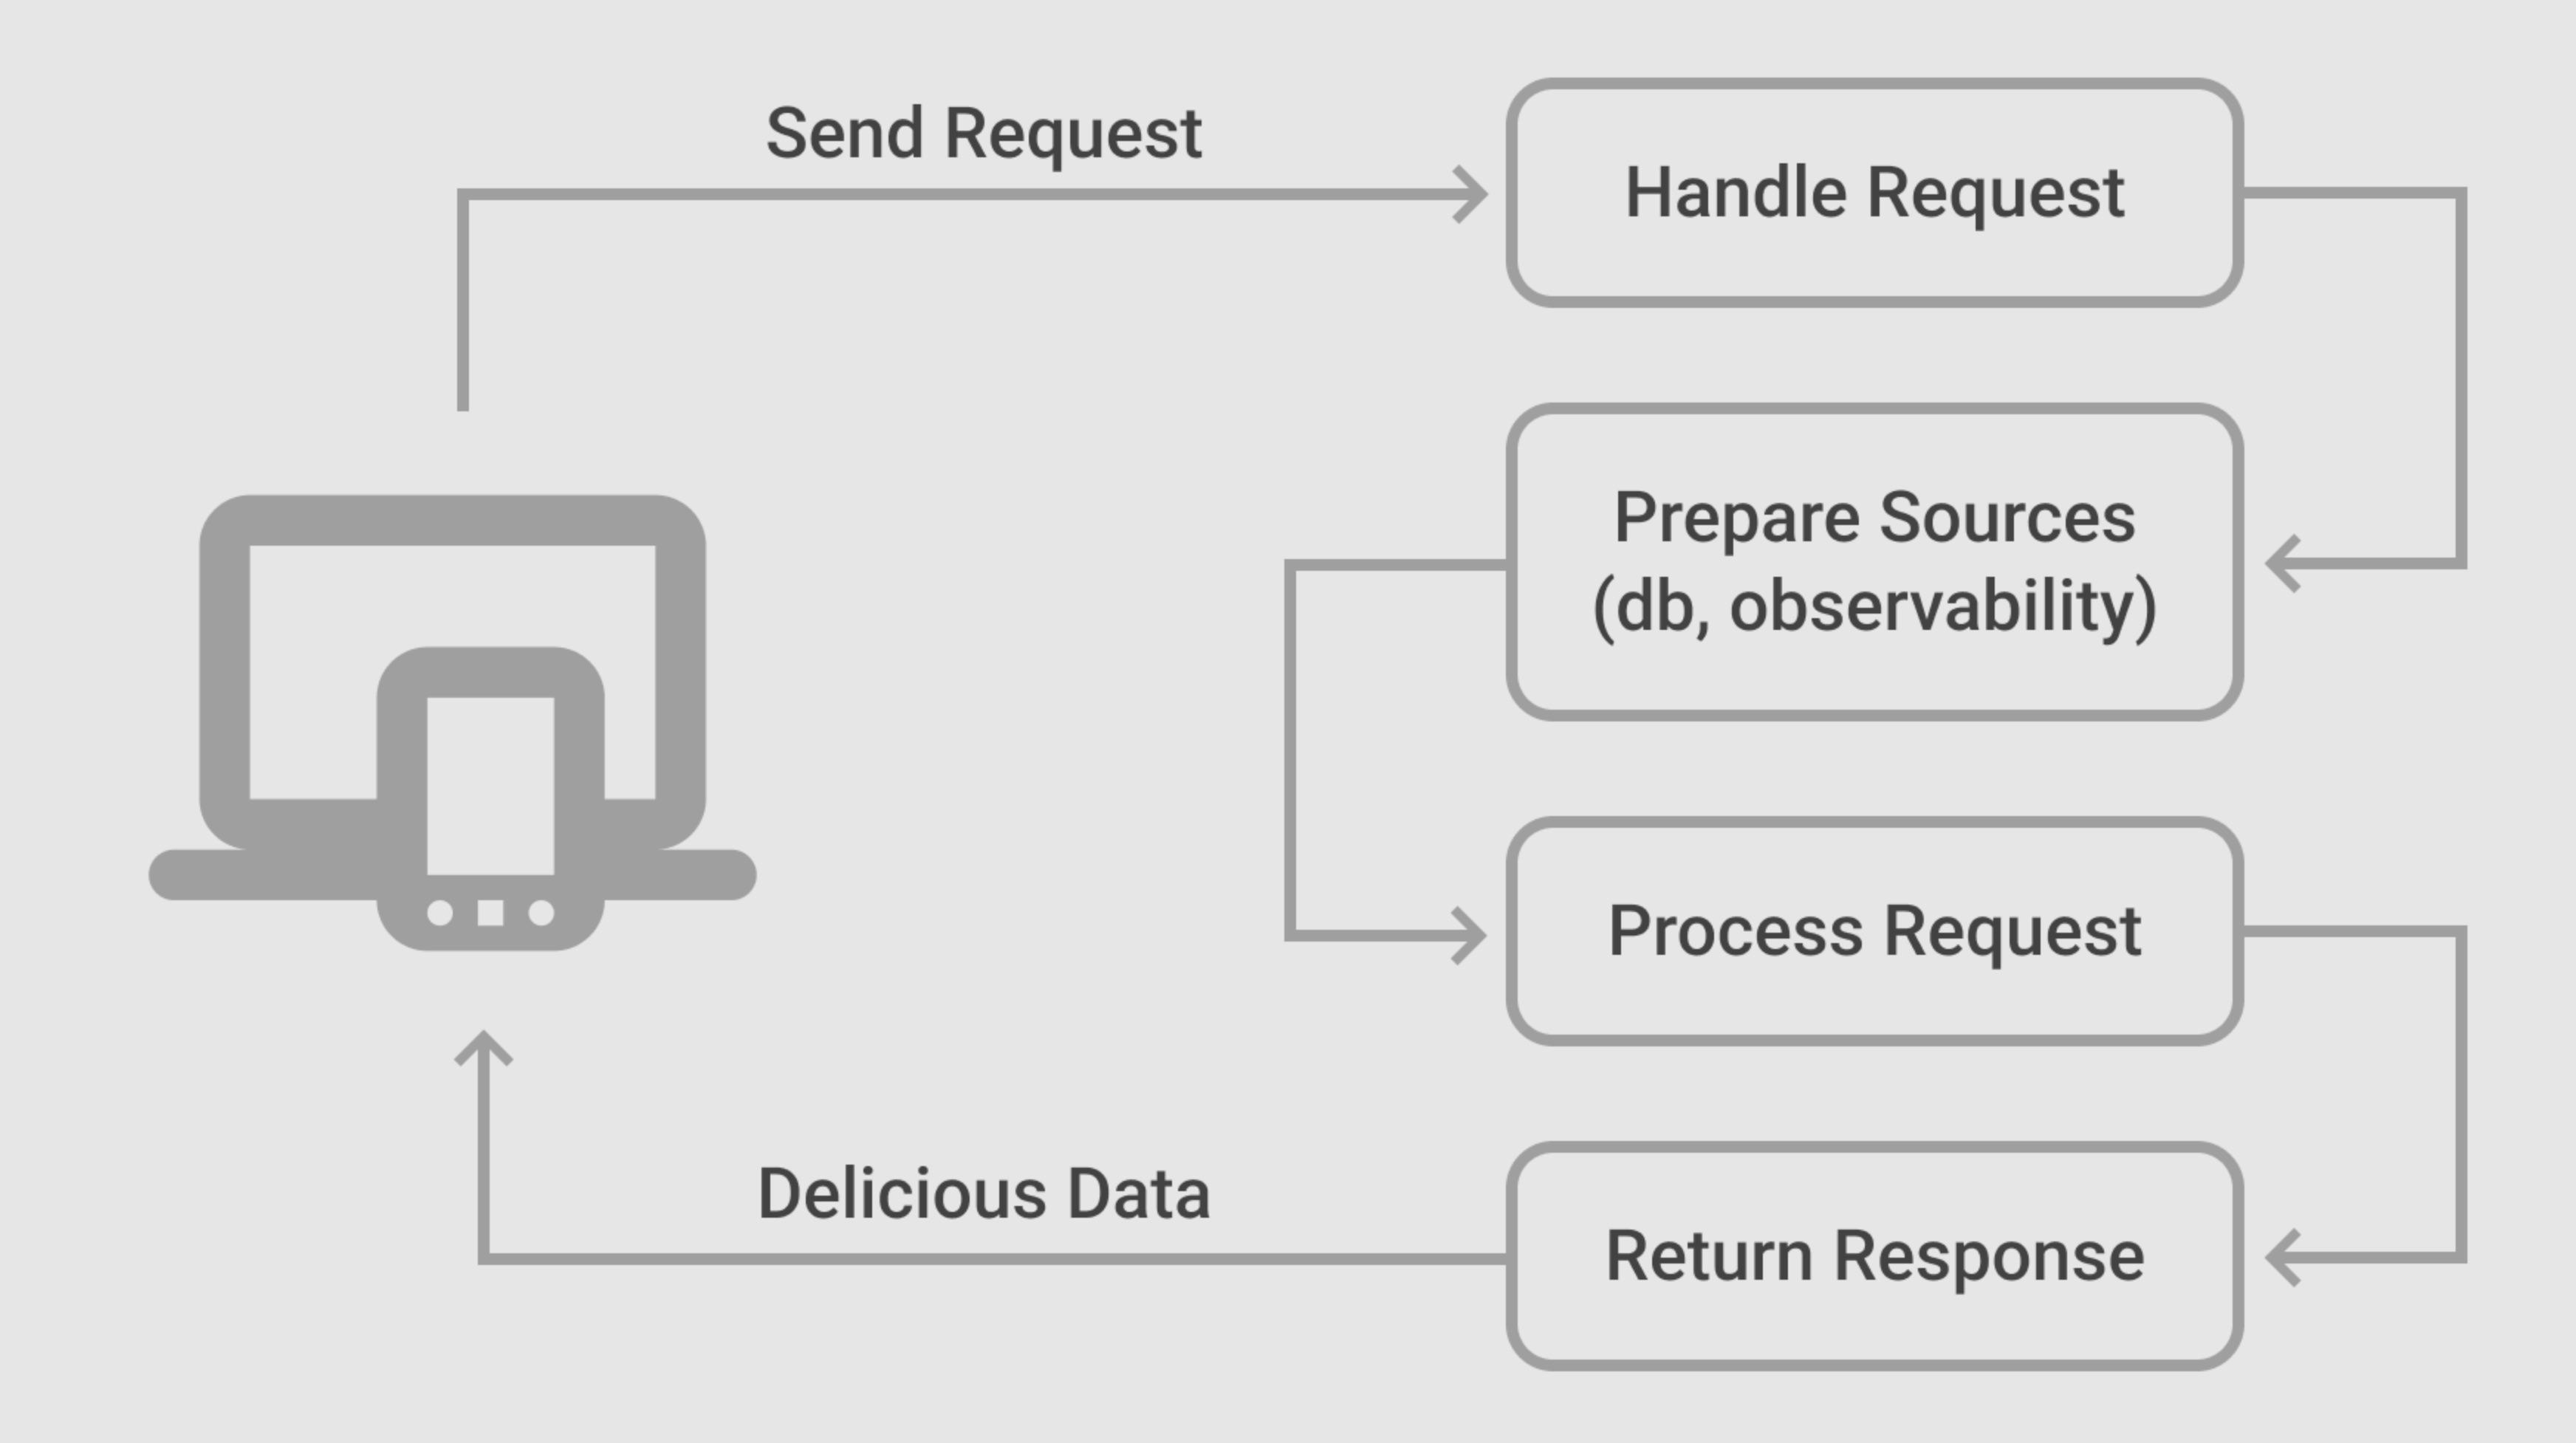
Caching allows you to reuse heavy resources like database connections, observability services, or prebuilt server instances between Lambda invocations. Without caching, these resources are re-initialized every time, which increases response times and slows down your Lambda function.
How does the AWS Lambda lifecycle enable caching?
After a Lambda finishes processing a request, the execution environment stays alive for several minutes (typically 15–40). During this time, any variables stored in the global scope remain available for reuse. If another request comes in before the Lambda “freezes,” your code can reuse existing instances instead of re-creating them, significantly improving performance.
How much performance improvement can caching provide?
In the example from the blog, reusing a cached database connection improved performance by more than 50% for subsequent Lambda requests. By avoiding repetitive setup tasks like reconnecting to the database or rebuilding services, caching significantly reduces latency.
What’s the best way to implement caching in AWS Lambdas?
- Declare connections or resource instances in the global context of your Lambda.
- Check if an instance already exists before creating a new one.
- Run expensive setup operations, such as establishing a database connection, only on the first invocation.
- Reuse the existing connection or instance for all subsequent requests while the environment remains active.
This ensures your Lambda avoids unnecessary work and delivers faster responses.
Is caching in Lambdas similar to the Singleton pattern?
Yes. This caching approach closely resembles the Singleton pattern, where a single instance of a resource is created and reused. In Lambda functions, the execution environment temporarily preserves these instances, which reduces cold-start overhead and optimizes performance for production workloads.